← Presentation home · Part 3 of 13
Why not fine-tuning?
Editorial update: The original slide describes our project experience. Fine-tuning can affect knowledge as well as style; the revised notes explain why we chose retrieval for this library.
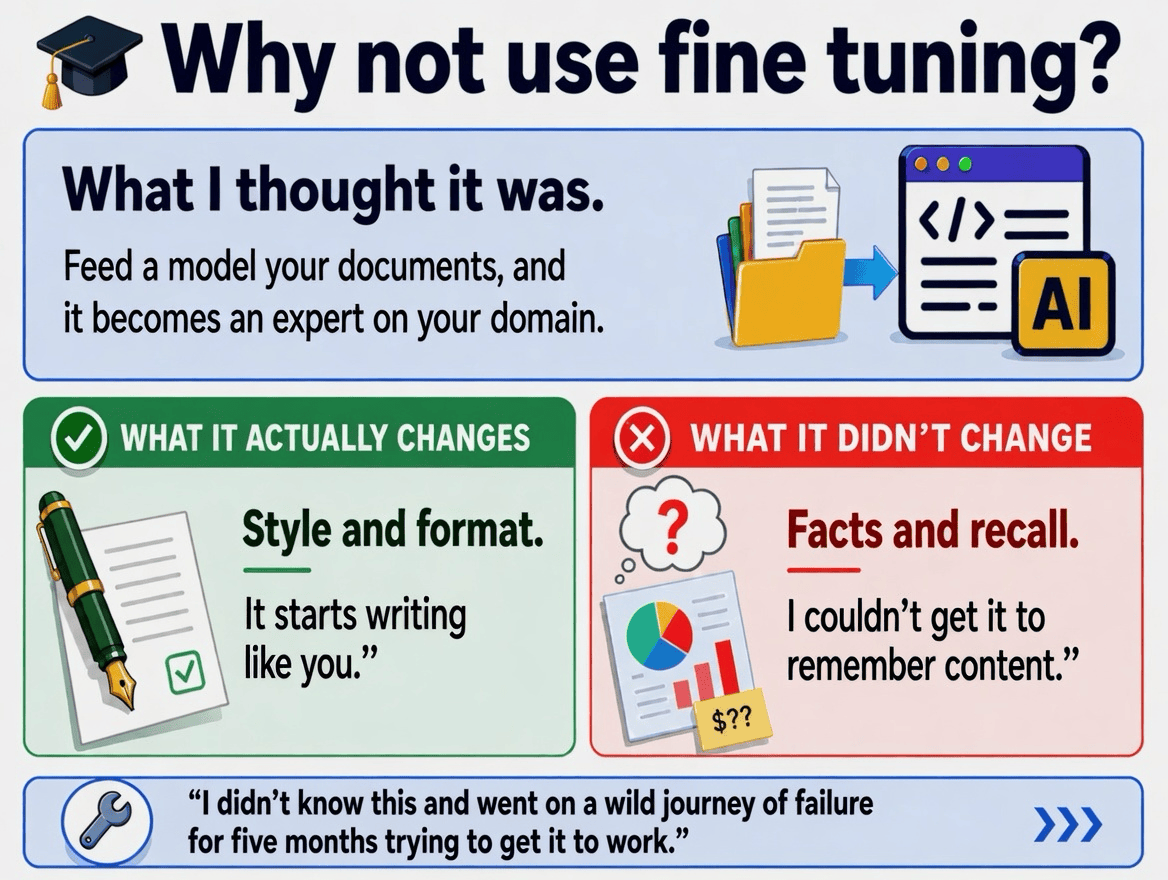
Why we chose retrieval over fine-tuning
The first approach was to fine-tune a model on our documents. Across the experiments described in this talk, the answers picked up the institutional voice but did not reliably reproduce the underlying facts. A polished answer was not enough.
What fine-tuning can do
Fine-tuning changes a model's weights using additional examples. It can improve style, format, task behaviour and some knowledge. How well it generalizes depends on the training data, model and evaluation. It is not a document database, and successful training examples do not prove dependable recall on new questions.
Why retrieval fit this library
Policies change. We wanted an answer tied to a document we could inspect and update. Retrieval supplies relevant passages at question time, giving us a more direct way to check the source of an answer.
It still has failure modes: the search can miss the right page, and the model can misread a page it receives. Both steps need testing.
Can the two approaches be combined?
Yes. RAFT is an example of training a model to use retrieved evidence more effectively. The question is whether that added training improves your measured results enough to justify maintaining it.
The practical lesson
Choose the simplest approach that meets the task's accuracy requirements. For our policy-library experiments, retrieval was the more useful starting point. The next page distinguishes that experience from the research evidence.